News · Articles
New open models this month (October 2026), and the hardware they need
Four real releases, from a 1 GB edge model to an 816B giant. Here’s which ones fit a home machine.
We earn from qualifying purchases via affiliate links. Disclosure.
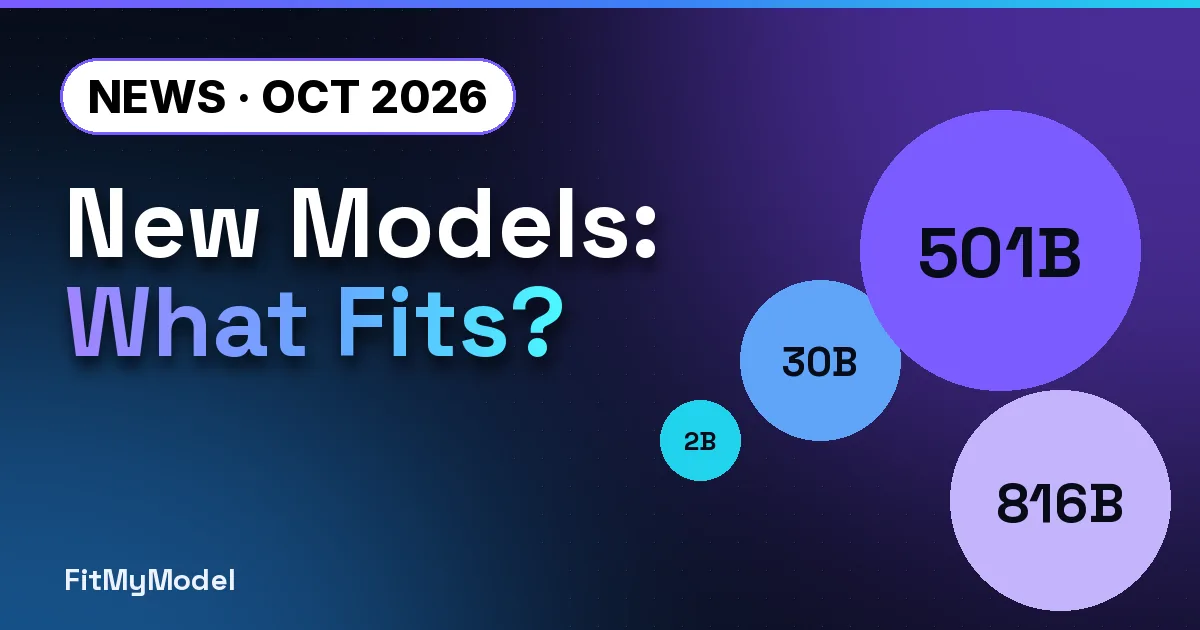
- Fits at home easily: Liquid AI’s LFM3 text model, about 1 GB at 4-bit (Oct 27).
- Fits a 24 GB GPU: Meta’s Muse Glimmer 30B, an 18 GB Ollama download (Oct 19).
- Not home hardware: Reflection’s Beam (501B) and Meta’s Muse Spark Open (816B).
October was a big month for open weights. Some of the new models fit on a phone, and some need a server room. Here’s the hardware reality check for each, using only what the makers and Ollama have published.
LFM3 (Liquid AI, Oct 27): tiny and everywhere
“the text model fits in about 1 GB at 4-bit precision.”
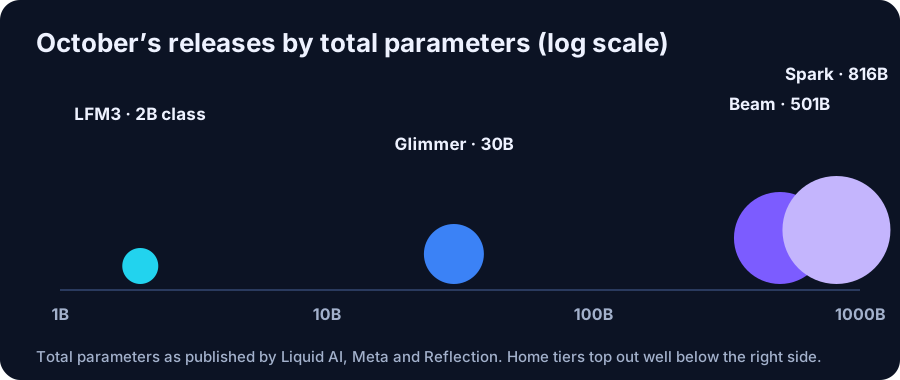
Six 2B-class models (text, vision, audio, omni and decision) share one backbone. The text model has a 256K context window. Any machine on this site can run it, and so can much smaller ones.
Muse Glimmer 30B (Meta, Oct 19): a 24 GB card’s new best friend
Meta calls it an on-device agentic model, Apache 2.0, “quantized to approximately 4-bit precision for efficient single-GPU inference.” Ollama lists muse-glimmer:30b at 18 GB with a 128K context. That puts it in our 24–32 GB tier, or a 64 GB unified box. It won’t fit fully on a 16 GB card.
Muse Spark Open (Meta, Oct 15): two Mac Studios
“Muse Spark Open is the first model in its class to run on your desktop using two Apple M5 Ultra Mac Studios with the latest MLX framework.”
816B total parameters (42B active) and a 1M-token context. That’s a cluster project, not a single-box one; see our clustering article.
Beam (Reflection, weights on Hugging Face Oct 16): datacenter scale
Beam is a 501B mixture-of-experts model with 23B active per token, a 1M-token context and an Apache 2.0 license, released in BF16, FP8 and NVFP4. Even at FP8, about one byte per parameter, that’s roughly 500 GB of weights (our estimate). That’s beyond any home tier we cover.
Hardware in this article
ASRock Intel Arc Pro B60 Creator 24GB
Price shown at Amazon
Sold at Amazon.
Check price at Amazon (opens in a new tab) ASUS Turbo Radeon AI Pro R9700 32GB
$1,999.99 Newegg · checked Oct 27, 2026, about 12:35 PM CT
Out of stock / unavailable
OUT OF STOCK when checked (search page)
Check price at Newegg (opens in a new tab)
Minisforum MS-S1 MAX 64GB / 2TB (Ryzen AI Max+ 395)
$2,599 Minisforum · checked Oct 27, 2026, 12:40 PM CT
Listed as available in the store data
Check price at Minisforum (opens in a new tab)More articles
Can a $600 mini PC really run local AI?
Yes, for small models, if you buy enough RAM. Here is what fits in a $607 Minisforum box, and what it can’t do.
Why VRAM matters more than GPU speed for LLMs
A faster GPU that can’t hold the model loses to a slower one that can. Here’s the one spec to read first.
Unified memory vs a GPU: Strix Halo, Mac and RTX compared
Capacity or bandwidth? Three ways to hold a model, compared on the two numbers that matter, straight from the spec sheets.
FAQ
Which October 2026 open models can I run at home?
LFM3 (about 1 GB at 4-bit, per Liquid AI) runs on almost anything. Muse Glimmer 30B (18 GB in Ollama) fits a 24 GB GPU or a 64 GB unified-memory machine.
Can I run Muse Glimmer on a 16 GB GPU?
Not fully on the GPU. Ollama lists the 30b tag at 18 GB, more than 16 GB of VRAM.