Analysis · Articles
Unified memory vs a GPU: Strix Halo, Mac and RTX compared
Capacity or bandwidth? Three ways to hold a model, compared on the two numbers that matter, straight from the spec sheets.
We earn from qualifying purchases via affiliate links. Disclosure.
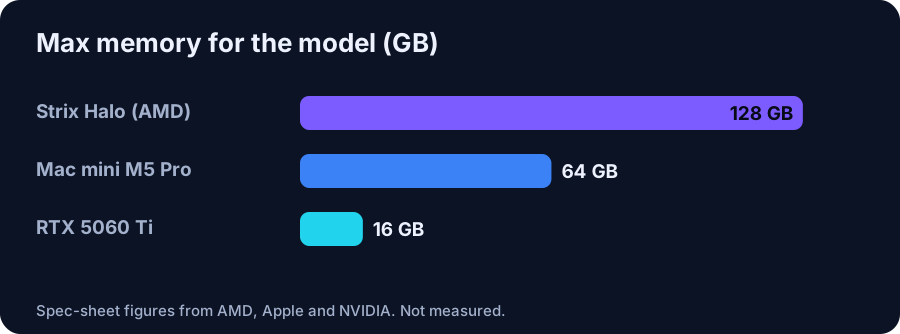
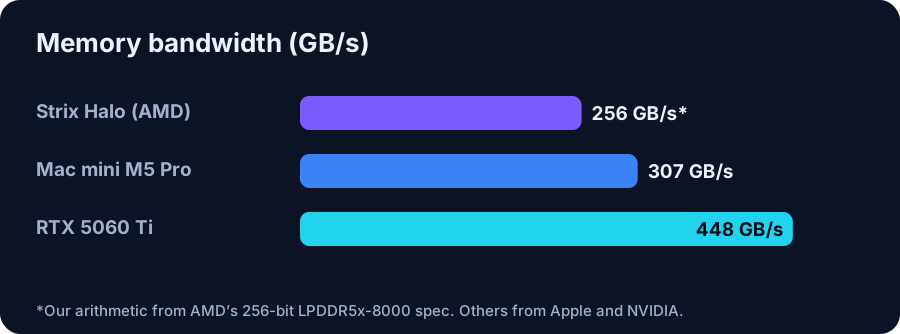
- Strix Halo: up to 128 GB; we work out 256 GB/s from AMD’s 256-bit LPDDR5x-8000 spec.
- Mac mini with M5 Pro: up to 64 GB at 307 GB/s, per Apple.
- RTX 5060 Ti: 16 GB at 448 GB/s, per NVIDIA. That’s the fastest of the three, but it has the least memory.
There are now two ways to give an AI model a home. A graphics card has a small room with a very fast door. A unified-memory machine has a huge room with a slower door. Which one you want depends on the model you’re moving in.
The spec sheet showdown
| Option | Max memory for the model | Memory bandwidth | Source |
|---|---|---|---|
| AMD Ryzen AI Max+ 395 (Strix Halo) | 128 GB (shared with the OS) | 256 GB/s (our arithmetic: 256-bit × 8000 MT/s ÷ 8) | AMD |
| Apple Mac mini, M5 Pro | 64 GB (shared with the OS) | 307 GB/s | Apple |
| NVIDIA RTX 5060 Ti 16GB | 16 GB VRAM | 448 GB/s | NVIDIA |
We list only the official figures. We haven’t measured any of these machines.
Capacity wins for big models
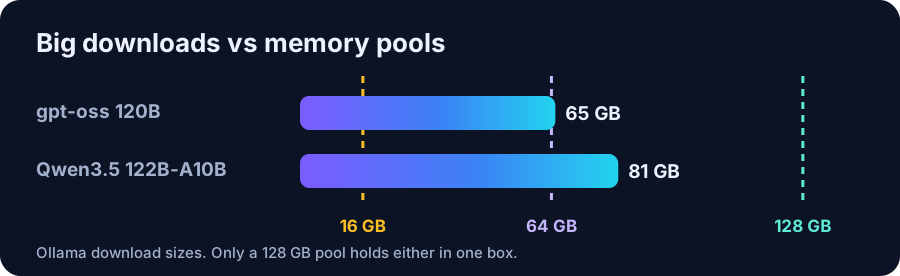
gpt-oss 120B is a 65 GB download in Ollama, and Qwen3.5 122B-A10B is 81 GB. Neither fits on a 16 GB card or in a 64 GB Mac. Only a 128 GB pool can hold them in one box. That’s the whole pitch for Strix Halo mini PCs like the Minisforum MS-S1 MAX and the GMKtec EVO-X2.
Bandwidth wins for small models
“Decode: Determines the tokens per second (TPS) and is memory-bound.”
If your model fits in 16 GB, the RTX card has the fastest memory of the three on paper. A 14 GB model on a 448 GB/s card should generate faster than the same model on a 256 GB/s pool (our estimate, based on the quote above, not a benchmark).
The trade-offs nobody puts on the box
- Soldered memory. On unified-memory machines you pick the size at purchase. You can’t upgrade it later.
- Expandability. The MS-S1 MAX’s store page lists a full-length PCIe x16 slot, which is unusual for a mini PC.
- Software. Check that your runtime supports your chip before you buy. This article doesn’t rate software support.
Hardware in this article
Minisforum MS-S1 MAX 128GB / 2TB (Ryzen AI Max+ 395)
$3,919 Minisforum · checked Oct 27, 2026, 12:40 PM CT
Caveat
Store data says estimated shipping late November. The 128GB / 4TB version was $4,199.
Check price at Minisforum (opens in a new tab)
GMKtec EVO-X2 128GB / 2TB
Price shown at Amazon
Sold at Amazon.
Check price at Amazon (opens in a new tab)
ASUS Dual GeForce RTX 5060 Ti 16GB OC
Price shown at Amazon
Sold at Amazon.
Check price at Amazon (opens in a new tab)More articles
Can a $600 mini PC really run local AI?
Yes, for small models, if you buy enough RAM. Here is what fits in a $607 Minisforum box, and what it can’t do.
Why VRAM matters more than GPU speed for LLMs
A faster GPU that can’t hold the model loses to a slower one that can. Here’s the one spec to read first.
Is 16 GB enough for local AI in 2026?
16 GB of VRAM is the new sweet spot. 16 GB of system RAM alone is the bare minimum. Here’s where the line falls.
FAQ
Is unified memory as fast as GPU VRAM?
Not on these spec sheets. AMD’s 256-bit LPDDR5x-8000 works out to about 256 GB/s, Apple lists 307 GB/s for M5 Pro, and NVIDIA lists 448 GB/s for the RTX 5060 Ti.
Which is better for gpt-oss 120B?
A 128 GB unified-memory machine. The 65 GB download does not fit on any single consumer GPU we list, or in a 64 GB machine.