Buying advice · Articles
Can a $600 mini PC really run local AI?
Yes, for small models, if you buy enough RAM. Here is what fits in a $607 Minisforum box, and what it can’t do.
We earn from qualifying purchases via affiliate links. Disclosure.
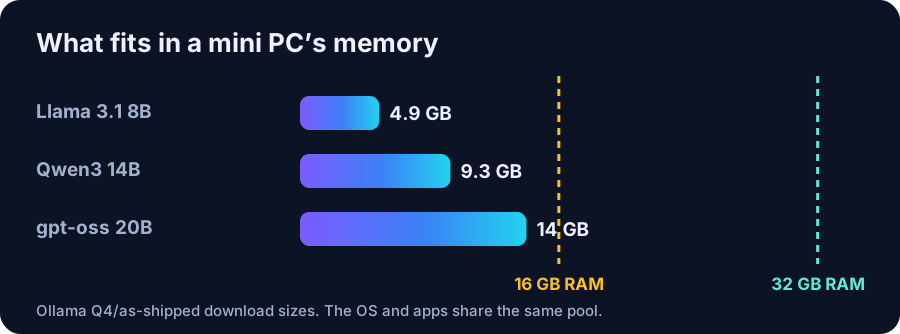
- Memory decides what fits. Llama 3.1 8B is a 4.9 GB download and Qwen3 14B is 9.3 GB in Ollama.
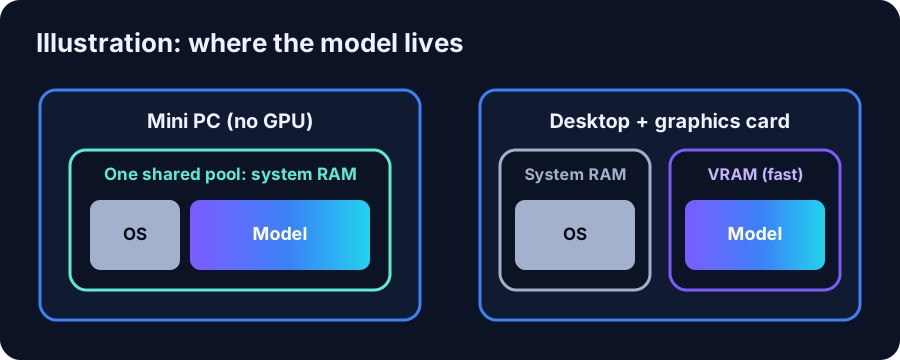
- Buy the 32 GB version. On a mini PC the OS, apps and model share one pool.
- Expect it to be slower than a GPU. We have not measured how much slower, so we show no speeds.
You don’t need a $3,000 workstation to talk to an AI model on your own desk. A $607 mini PC can hold one. The catch is how it holds it: with no graphics card, the whole model lives in ordinary system RAM.
What $600 buys today
On the Minisforum store (Oct 27, 2026, 1:06 PM CT), two boxes sat right around $600: the NAB6 Lite with a Core i5-12600H, 32 GB RAM and a 500 GB SSD at $607, and the UM780L Slim with a Ryzen 7 7840HS, 16 GB RAM and a 1 TB SSD at $615. Neither has a separate graphics card.
What fits in 32 GB
Ollama lists Llama 3.1 8B at 4.9 GB and Qwen3 14B at 9.3 GB at Q4_K_M. Both fit in 32 GB with plenty left for Windows and a browser (our estimate). Even gpt-oss 20B’s 14 GB download fits in the pool, though it will be the slowest of the three. In 16 GB, the 8B model is the comfortable choice; a 14 GB model would leave the OS almost nothing.
Ollama’s own FAQ explains how to check where a model landed: ollama ps shows 100% CPU when the model is in system memory.
Why it will feel slower
“Decode: Determines the tokens per second (TPS) and is memory-bound.”
Every new word the model writes means reading its weights from memory again. A graphics card’s memory is built for that kind of traffic; laptop-class system RAM is much slower. So a mini PC answers, but more slowly than a GPU would. We haven’t timed either box, so we won’t give you a number.
Who should buy one
Buy a $600 mini PC if you want a quiet, always-on helper for summaries, drafts and private chat with an 8B–14B model. If you want 20B+ models at a snappy pace, or image generation, a 16 GB GPU is the better use of money. If you want the big models, look at 128 GB unified-memory boxes.
Hardware in this article
Minisforum NAB6 Lite, Core i5-12600H, 32GB RAM / 500GB SSD
$607 Minisforum · checked Oct 27, 2026, 1:06 PM CT
Listed as available in the store data. Integrated graphics only: models run from system RAM.
Check price at Minisforum (opens in a new tab)
Minisforum UM780L Slim, Ryzen 7 7840HS, 16GB RAM / 1TB SSD
$615 Minisforum · checked Oct 27, 2026, 1:06 PM CT
Listed as available in the store data. Integrated graphics only; 16 GB is shared by the OS and the model.
Check price at Minisforum (opens in a new tab)
ASRock Challenger Intel Arc B580 12GB
$329.99 Newegg · checked Oct 27, 2026, about 12:35 PM CT
Sold by Newegg, seen on the product page
Check price at Newegg (opens in a new tab)More articles
Why VRAM matters more than GPU speed for LLMs
A faster GPU that can’t hold the model loses to a slower one that can. Here’s the one spec to read first.
Unified memory vs a GPU: Strix Halo, Mac and RTX compared
Capacity or bandwidth? Three ways to hold a model, compared on the two numbers that matter, straight from the spec sheets.
Is 16 GB enough for local AI in 2026?
16 GB of VRAM is the new sweet spot. 16 GB of system RAM alone is the bare minimum. Here’s where the line falls.
FAQ
Can a mini PC without a graphics card run AI models?
Yes. Runtimes like Ollama can run a model entirely from system memory; ollama ps then shows 100% CPU. It works, but it is slower than a GPU.
Is 16 GB of RAM enough for a local AI mini PC?
For an 8B model (4.9 GB in Ollama), yes. For 14B and larger, get 32 GB so the operating system still has room.